CS-EVAL CYBERSECURITY EVALUATION
Garrulus-Agent
Source-Grounded Cybersecurity AI Agent
1 / 55Overall rank
99.38Overall score
The first model to score a perfect 100 in six categories and cross the 99 mark overall.
See the official leaderboardEngineering approach
Emrah Dündar
Six perfect scores, lowest category 98.54
CS-Eval: open evaluation by researchers from Alibaba Group, Fudan University and the University of Chinese Academy of Sciences. 11 domains, 42 subdomains, 4,369 questions.
- 100System and software
- 100Encryption
- 100AI and network
- 100Business continuity
- 100Security architecture
- 100Supply chain
| Category | Score |
|---|---|
| System and software security basics | 100 |
| Encryption and key management | 100 |
| AI and network security | 100 |
| Business continuity and recovery | 100 |
| Security architecture design | 100 |
| Supply chain security | 100 |
| Data security and privacy | 99.60 |
| Infrastructure security | 99.17 |
| Threat detection and prevention | 99.08 |
| Access control and identity management | 98.85 |
| Vulnerability management and pentesting | 98.54 |
First Among 55 Entries
CS-Eval Overall Ranking, Top 6 Results
- 1Garrulus-AgentEmrah Dündar · independent developer99.38
- 2RunjianMenshen98.49
- 3China Unicom Digital TechnologyMogong V3-Agent98.47
- 4China Telecom Security TechnologyJianwei Agent98.33
- 5QAXQGPT V5 QAgent98.26
- 6AntiyLandi N297.96
0.89 points ahead of second place, the widest gap between consecutive ranks in the top six.
Visualization: CS-Eval overall ranking, 10 November 2026
LLM Engineering & Agentic AI
The engineering disciplines behind Garrulus-Agent.
Model Engineering
- Open-Weight LLM Selection
- Prompt Engineering
- Inference Optimization
Agentic AI
- Planning & Tool Use
- Source-Grounded Verification
- Agent Orchestration
Evaluation Engineering
- Benchmark-Driven Development
- Held-Out Evaluation
- Experiment Automation
Human-in-the-Loop: Goals, technical decisions and results are mine.
The official leaderboard
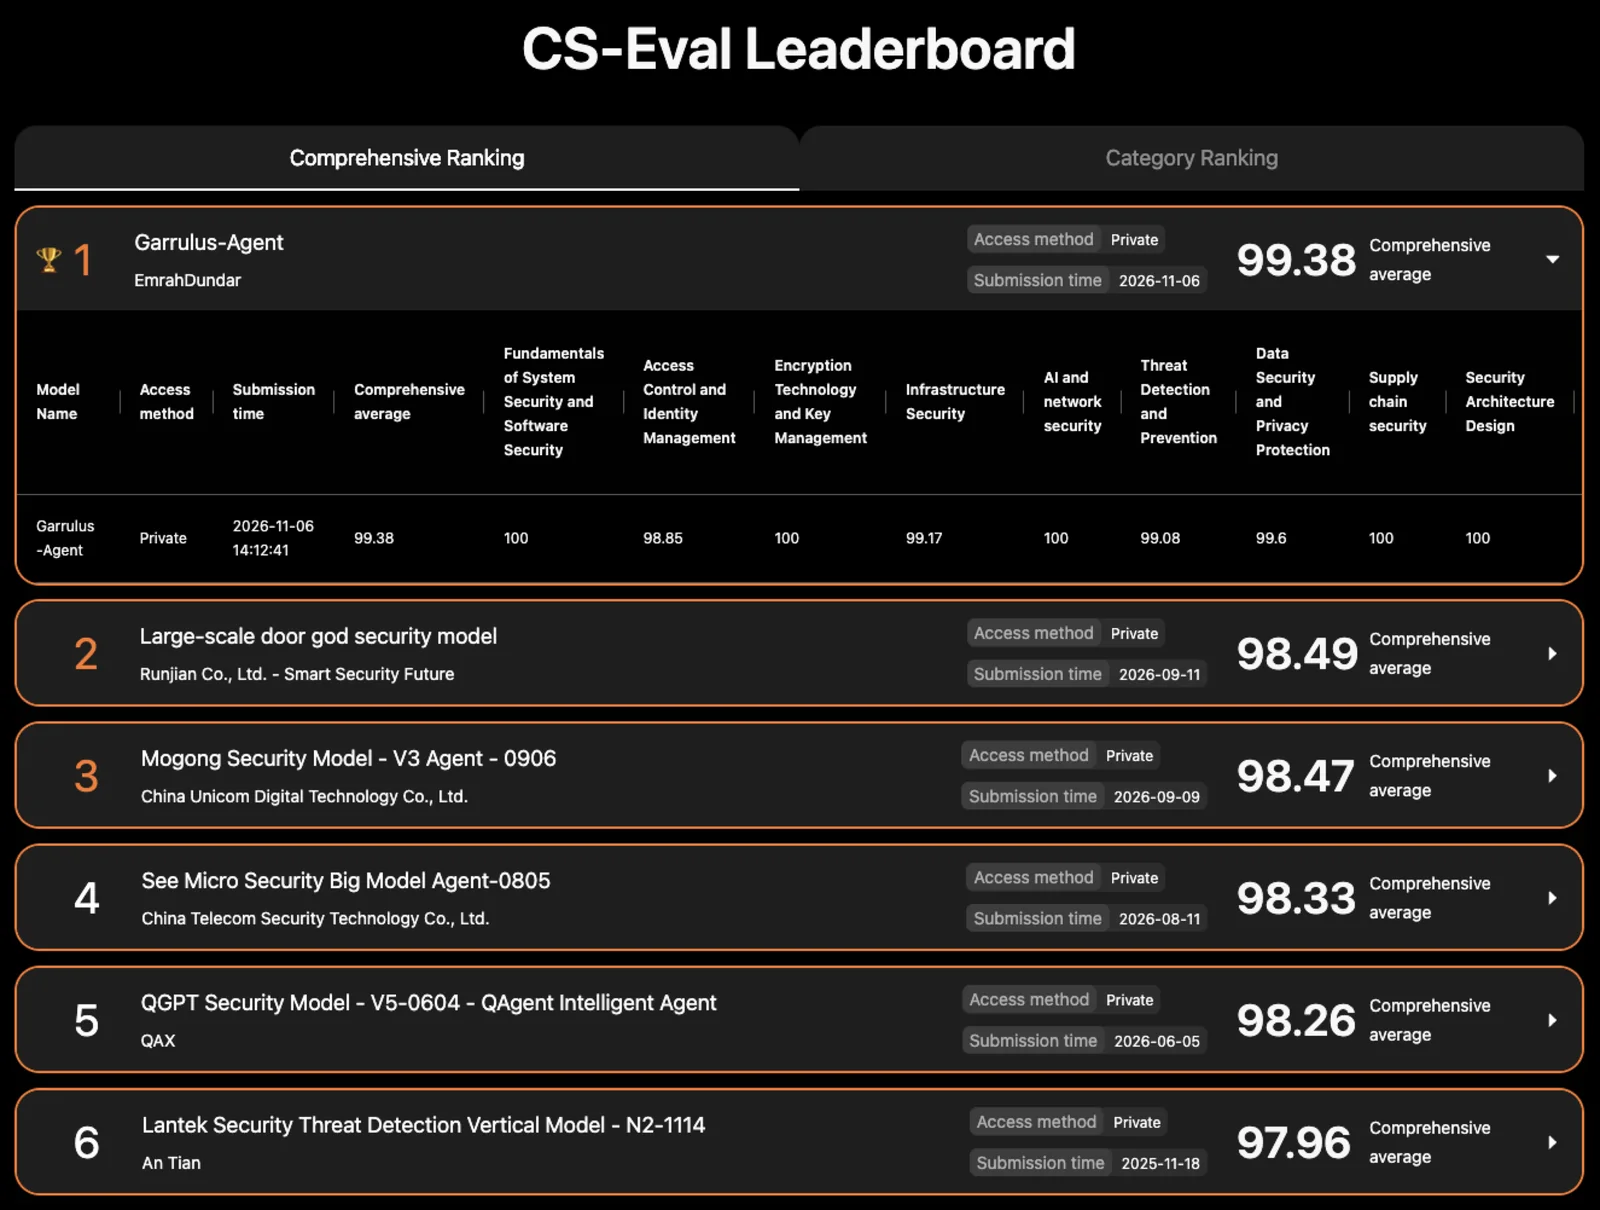
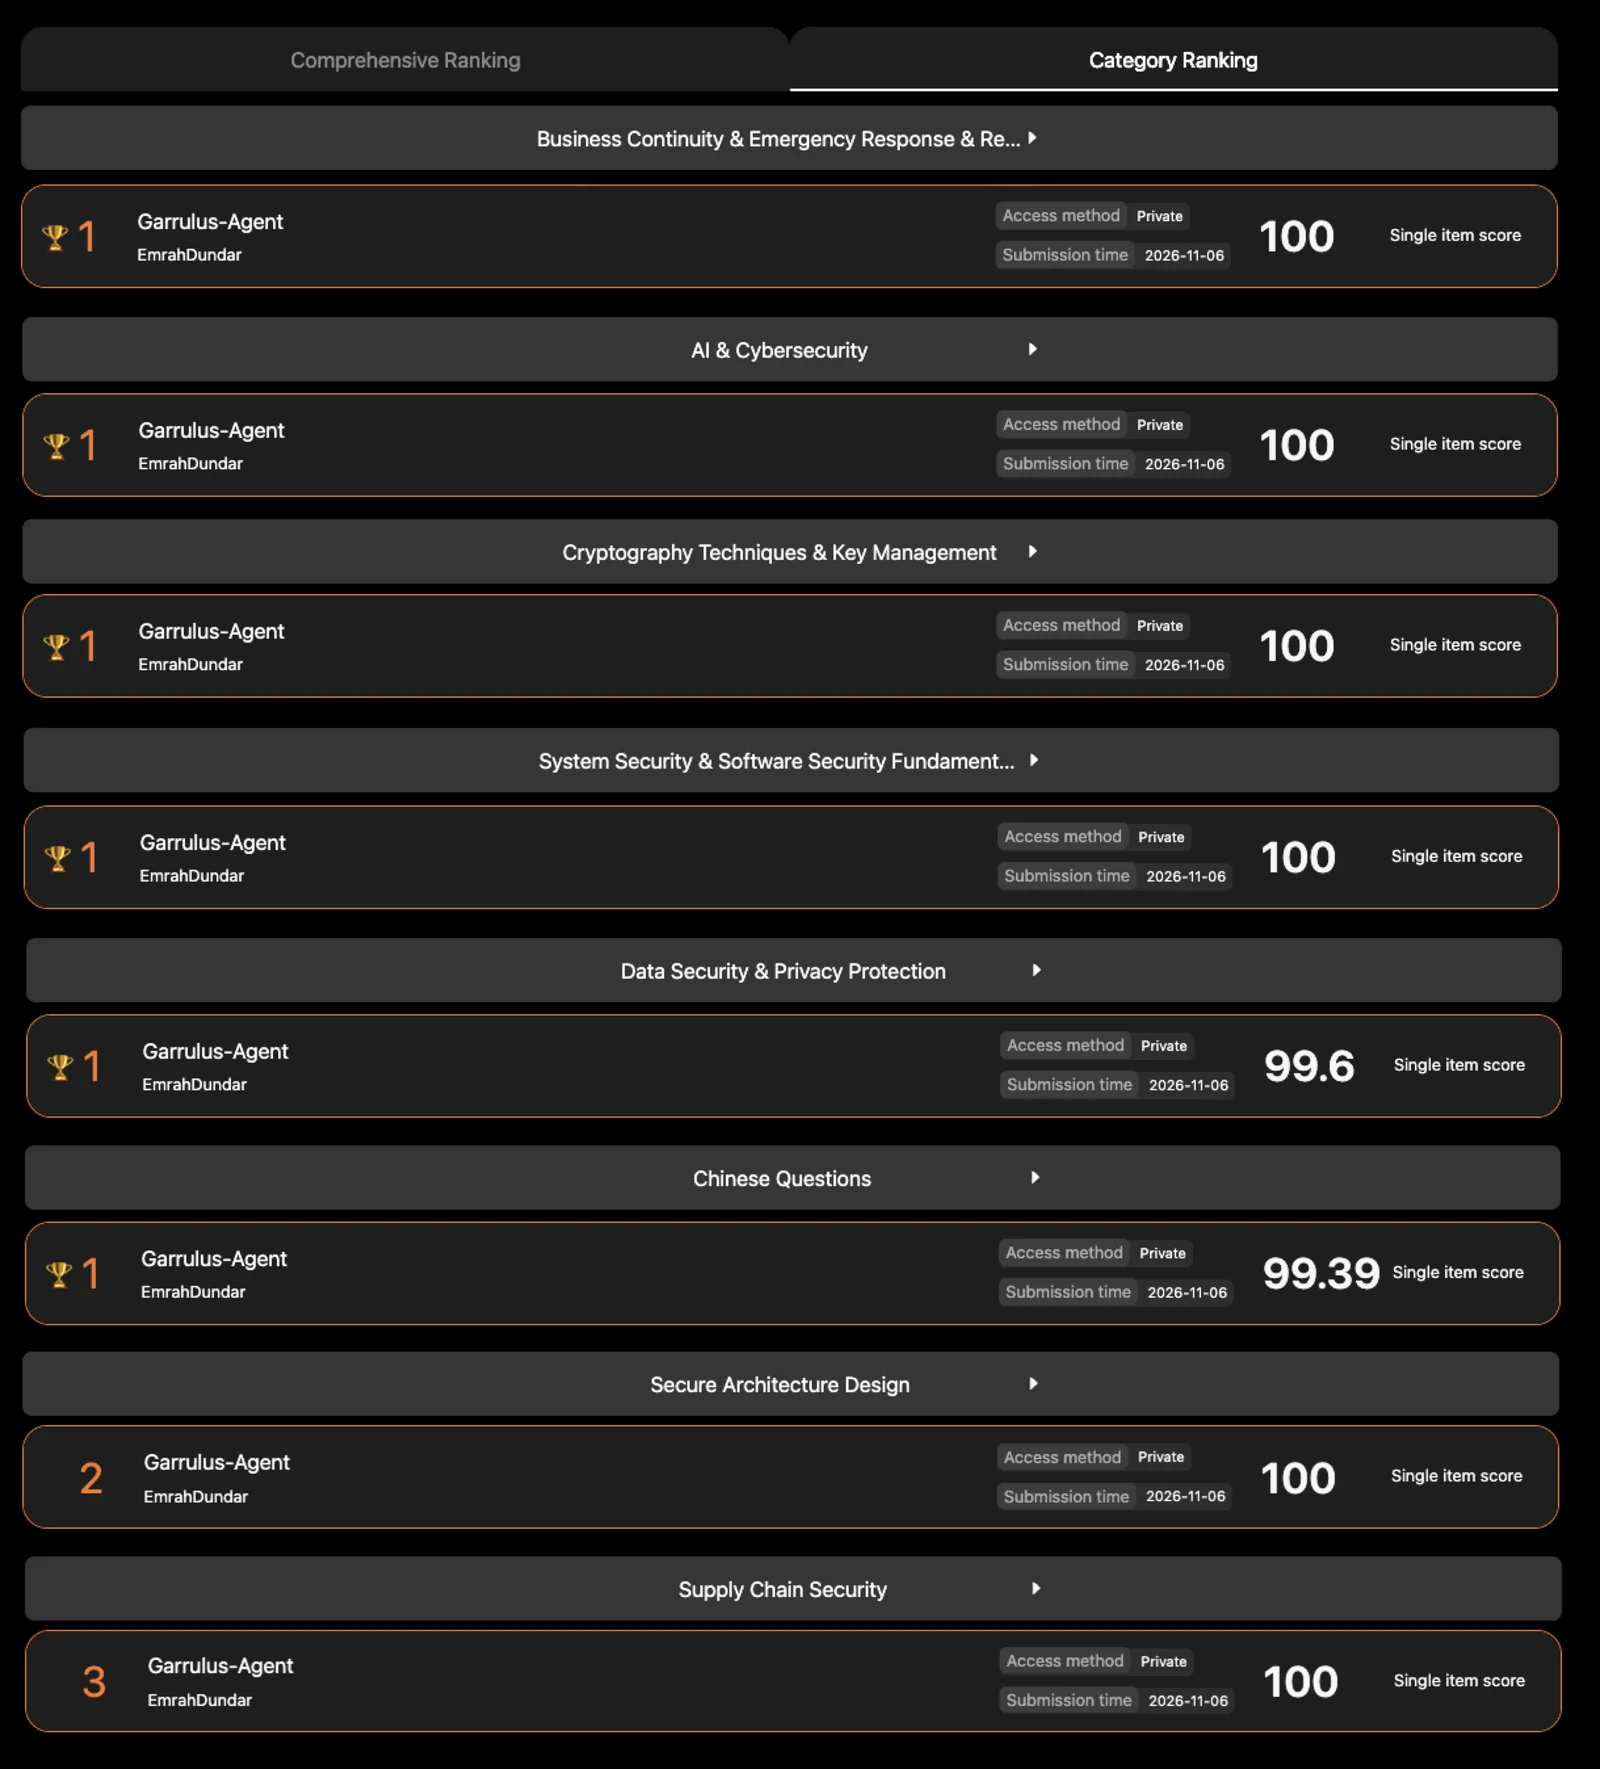
cs-eval.com, 10 November 2026. Screenshots cropped, data unchanged. The Chinese Questions row is a language subset, not one of the 11 categories. English model names on the leaderboard screen are the site's automatic translation.
With the right engineering, agent systems and disciplined evaluation, open-source models become high-performing, domain-focused AI solutions.
Emrah Dündar